Episodic memory for coding agents: What survives your sessions
Episodic memory is a coding agent's record of past sessions. Saved lessons can outlive the transcripts behind them, so keep each lesson tied to its source.
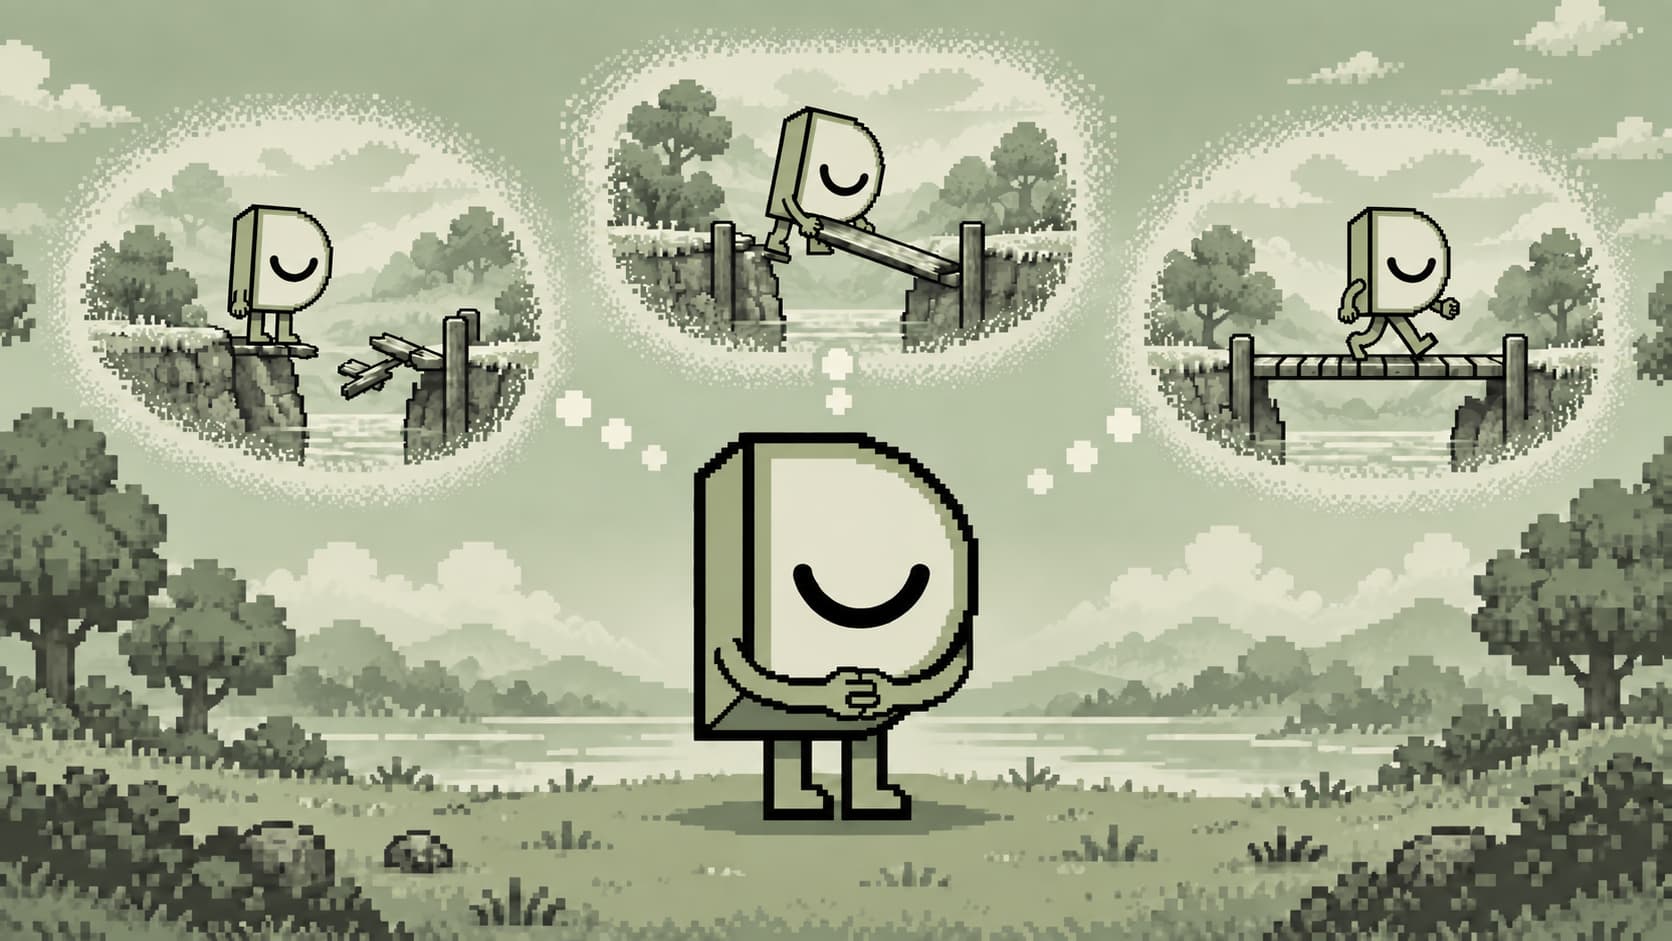
Your coding agent saves one line to MEMORY.md telling future sessions to use make test-int. A month later the command fails, and you want to know what problem make test-int solved in the first place. By then Claude Code may have cleaned up the transcript, since cleanupPeriodDays defaults to 30 days, while the one-line lesson stays in memory.
The lesson came from an ordinary session. The agent ran pytest tests/integration, and the tests couldn't reach their database. The agent then read the Makefile and ran make test-int, a target that starts the services the tests need, and the suite passed. Episodic memory is a coding agent's record of specific past events, such as the command that failed, the file it read, and the fix, kept with when they happened.
A saved summary tends to lose the why. The note that says to use make test-int doesn't mention the database the tests couldn't reach. We think you should keep the raw episode and point each lesson back to it, so the reason is still there on the day the lesson stops working.
The CoALA framework for language agents separates episodic memory from semantic memory, which holds facts, and procedural memory, which holds ways to act in the model's weights and the agent's code. Our test session can feed all three.
| Memory type | What it stores | Where it often lives for a coding agent | Our test session |
|---|---|---|---|
| Episodic | Specific past events and when they happened | Session transcripts | The transcript JSONL |
| Semantic | Facts | Memory files, docs, a knowledge base | The fact "make test-int starts the services the integration tests need" |
| Procedural | Ways to act | Model weights and agent code | The instruction "Run integration tests with make test-int" |
What your agent records while it works
To check why your agent chose make test-int, start with the conversation where it found the command. Claude Code saves session transcripts under ~/.claude/projects/ by default, and each line of a session's .jsonl file is a JSON record of a message, tool activity, or session metadata. Open the file and you can follow the failed run, the Makefile read, and the command that worked. If you write a tool to read these files, plan for the format to shift, because Claude Code's docs call the transcript an internal format that can change between versions.
Codex writes the same kind of record, which it calls a rollout, as JSONL under ~/.codex/sessions/YYYY/MM/DD/, with a timestamp and thread ID in each filename. Archived sessions move to archived_sessions.
An episode doesn't have to span a whole conversation. Generative Agents stores observations as natural-language descriptions with creation and last-access timestamps. Graphiti can treat a message, JSON document, or block of text as an episode, keeping the raw content, a source description, the original document's time, and links to extracted facts. Those fields let a retriever find an observation by time or follow a fact back to its source.
How does your agent pick which past episode to recall?
Say your next request is "run the integration tests before you push." Generative Agents gives a worked design for choosing which memory comes back. The system scores each memory for recency, importance, and relevance, rescales each term across the candidates so the highest becomes 1 and the lowest 0, and adds the three with equal weights.
score = recency + importance + relevance
The paper's agents live in a simulation, so recency decays by a factor of 0.995 for every game hour since the agent last retrieved a memory. If we treat a game hour as an hour of wall-clock time, a memory last retrieved a day ago scores 0.887, and one last retrieved a week ago scores 0.431. Retrieving a memory restarts its clock, so a useful old episode can keep coming back.
The model rates importance from 1 to 10 when the system writes a memory, with brushing teeth as the paper's example of a mundane event. For relevance, the system turns the query and each memory into embeddings and compares them with cosine similarity, which lets the retriever favor a test-command memory over an unrelated CSS fix even when the query uses different words. The released Generative Agents code departs from the paper, with last-accessed order for recency and unequal weights.
If you remember make test-int, a text search finds the earlier conversation. But what if you only remember that the tests couldn't reach the database? Then you need a search that compares meaning, since keyword and semantic search solve different parts of the problem. Letta Code's recall subagent combines the two on its cloud API, while its local backend uses text matching alone. The Generative Agents authors list retrieval misses among their most common errors. If your agent runs bare pytest again tomorrow, the lesson may still be in memory and rank below other results, so check the search results before you conclude the agent forgot.
What a new session starts with
A note saying to use make test-int may be all you need tomorrow. If the command fails, though, you'll want the investigation behind the note. Did the target start a missing database? Did your agent change a configuration file along the way? Resuming the earlier conversation in Claude Code lets you continue the investigation, but Claude Code summarizes a conversation that grows too long, a process called compaction, so your resumed agent might see the successful command while the original error survives only in the transcript.
A fresh conversation starts from lessons saved separately. Claude Code's auto memory loads the beginning of MEMORY.md and lets the agent read more detailed topic files as needed. When you enable memories in Codex, its memory_summary.md guides the agent toward more detailed records. In both tools, a link or path from the lesson back to the session gives the agent somewhere to look for the reason. Check which files the agent read before you trust its account of the earlier work.
What does compaction do to your agent's memory?
The failing test output and the Makefile contents compete for room with everything the agent reads afterward. When the conversation nears the limit of the context window, the space the model can see on each call, compaction replaces the in-context history with a summary.
Claude Code clears older tool outputs first, then writes a structured summary if it still needs room. Afterward, Claude Code reloads the project-root CLAUDE.md, unscoped rules, and auto memory from disk, and re-reads up to five files, most recently modified first, with files over 5,000 tokens coming back as path references. Your Makefile can come back with its contents if it fits. The summary may preserve the failing test output, or your agent can run the tests again.
Codex compacts remotely for OpenAI and Azure Responses providers. On the local path for other providers, Codex asks the model for a handoff summary and keeps up to 20,000 tokens of your recent messages beside it, so your request to run the tests can survive word for word while the account of the failed run depends on what the summary kept.
What happens when the session fills up again? In both tools, the next compaction reads the first summary in place of the history it replaced, plus the recent messages the system kept. If the first summary dropped why make test-int worked, the second can't recover the reason.
The Agentic Context Engineering paper, or ACE, studied a related failure during repeated rewrites of an agent's accumulated context. In its AppWorld case study with Dynamic Cheatsheet, the context held 18,282 tokens at step 60 and scored 66.7 accuracy. One rewrite later it held 122 tokens and scored 57.1, below the 63.7 baseline with no adaptation.
ACE calls the drop context collapse. ACE studied an agent rewriting its own accumulated context, which differs from compaction in a coding session, and we haven't found a study of the coding case. We read ACE's example as a reason to check what repeated summaries drop, and it doesn't tell us how much detail your own session loses.
The original evidence can survive compaction. Claude Code's checkpoint docs say that when you summarize from /rewind, which works like a targeted /compact, the original messages stay in the transcript, where a later pass can read the failing test output as long as the file survives.
Turning a session into a lesson you can reuse
Once the tests pass, you probably want a shorter memory than the whole investigation, one that points back to the session behind it. Generative Agents calls the step from episodes to lessons reflection. When the combined importance of recent events crosses a threshold, the system asks the model what it can learn from recent memories, retrieves evidence for those questions, and writes insights with citations to the records it used. If three sessions showed the same test setup, the insight would cite all three.
make test-int starts the services the integration tests need. (because of 1, 2, 3)
The numbers point to the episodes behind the lesson, so a later pass knows where to look when it needs to check or revise the insight. CoALA files reflections like this one under semantic memory.
Reflection can also happen after the session ends, in what our Knowledge Capture post calls background capture. If you enable Codex's memory pipeline, which is off by default, a separate agent reviews eligible past sessions when your next top-level session starts. The agent writes memories and summaries, consolidates selected results with paths back to their source sessions, and has explicit permission to save nothing. Reading the transcript gives that agent the database error and the Makefile contents, which an earlier summary reading only "fixed tests" would have lost.
A saved reflection can also introduce a mistake. ExpeL extracts insights by comparing failed and successful attempts, and in one comparison on the HotpotQA question-answering benchmark, adding self-reflections from Reflexion reduced success from 39.0 to 29.0. The authors suggest those reflections sometimes hallucinated, and the comparison covers one environment. Before you pass the test lesson to a teammate, compare the saved explanation with the failed run and the Makefile.
Our Maintenance post explains why we keep the original inputs behind a memory. A later pass can check a lesson against them and correct it when a summary missed something. Rereading those inputs costs model time, and someone has to store them.
How long transcripts and lessons last
Your agent can keep the make test-int lesson in MEMORY.md long after Claude Code's cleanup removes the transcript that explains it. Claude Code's cleanupPeriodDays defaults to 30 days, and a background sweep can remove eligible transcripts after that. The retention rules include exceptions for Desktop and Cowork sessions, settings can pause cleanup, and bare mode skips it. The sweep leaves auto memory alone.
Codex's memory pipeline runs on its own clocks, set in types.rs. Phase 1 extracts only rollouts whose threads had activity within memories.max_rollout_age_days, 10 days by default, and have sat idle for at least 6 hours. An older rollout never reaches extraction, even if you can still open its file. The pipeline also stops selecting a memory after 30 days without use by default.
Once you delete the only transcript, you'll have to rebuild the investigation from whatever evidence remains, so set retention to match how long you may need to look back.
Sharing the lesson with your team
Your test transcript contains more than a command. The failing run may print details you'd leave out of a short lesson, and Claude Code stores transcripts in plaintext, so longer retention keeps those details on disk longer. Before another model reads your transcript, check which parts it receives. Codex's extraction step keeps messages and tool activity, drops reasoning, developer-role messages, and compaction items, and redacts secrets that match its detection patterns.
Auto memory stays on your machine, so a lesson Claude Code saves there doesn't reach your teammate's agent. To help that agent, you need to put the lesson somewhere every agent on the team can read.
With Dosu, the lesson can reach your team through notes from finished sessions. The Dosu CLI installs a session-end hook for Claude Code, Codex, and Cursor that queues each finished session for background study. Study runs on your machine, reads the user and assistant turns, drops tool calls and tool output, and redacts secrets before any text goes to Dosu's LLM gateway. Study can save notes to your team's Library, and each note records an author and a timestamp.
Study skips the tool output that holds the raw database error and the Makefile contents, so the reason behind make test-int gets into a note only if the conversation stated it, for example when the agent explained in its reply that the target starts the database. The gap is another reason to keep your transcript.
A note from a session in a repository connected to the Library stays tied to your branch until the branch's pull request merges, and then Dosu promotes it into a candidate Topic for the Library. A note from a session outside a connected repository is readable by Library members right away. Your teammate's agent looks for either one through read_knowledge, because the CLI's standing rule tells agents to read shared knowledge before non-trivial work.
Shared memory also needs access boundaries. OWASP's guidance on memory and context poisoning includes isolating user sessions and domain contexts. Everyone in your organization can read an internal Library, the default in Dosu, while only the people you add can read a private one. As a lesson moves from a private session into team knowledge, check who can read the source and who can read the note.
Try following one of your own sessions
Pick a recent investigation where your agent learned something, find its transcript under ~/.claude/projects/ or ~/.codex/sessions/, and follow the lesson into your memory files. Can you still find the output that explains the fix? If not, check your retention settings, and in Codex, whether memories are on and the age window covers the session.
The test command in our example started as an event in a transcript. Saved as "make test-int starts the services the integration tests need," the lesson is a fact about the repo, semantic memory. Saved as an instruction to run make test-int, the lesson works as procedural memory wherever you keep it. Keeping the episode lets you check the evidence behind either one.
Connect your coding agent to Dosu. If you have the Dosu CLI, run dosu upgrade, then dosu setup, and accept setup's offer to study the sessions you've run so far. Then pick an investigation you remember and check whether the note Dosu saved explains the fix, while the transcript is still on disk to compare against.
Found this article helpful?
Share it with your network to help others discover valuable insights.
Want more like this? Subscribe via RSS
Related Articles
September Drop: Dosu goes back to school
Sep 23, 2026 / 6 min read
Dosu studies coding sessions, shows what your agent reads, and makes your credits go further.
How to Build Agent Memory: Maintenance
Sep 21, 2026 / 7 min read
How to keep agent memory useful as things change: preserve evidence, scope updates, choose maintenance triggers, and measure whether memories still help.
How to Build Agent Memory: Search & Retrieval
Sep 13, 2026 / 9 min read
How agents find and use what they've learned: choosing a search strategy, returning useful context, and balancing precise evidence with higher-level understanding.
A Correct Translation Can Still Be Wrong in Meaning
Sep 8, 2026 / 4 min read
A settings label translated 'correctly' and still meant the wrong thing. The fix wasn't a better dictionary, but context — and it's already scattered across your code, PRs, and conversations.